Social Media Sentiment Analysis Explained for Ops Teams
"Learn how social media sentiment analysis works, from models to sarcasm and multimodal signals, and how ops teams turn it into triage and routing."
Your unified inbox is quiet until it isn't. A billing complaint appears under an Instagram post, X fills with outage mentions, and a TikTok creator publishes sarcastic praise that signals frustration. In Discord, members bury a feature request inside a long conversation, while WhatsApp receives messages in mixed languages and slang. By the time a human reviewer sees the pattern, the support SLA may already be under pressure.
Social media sentiment analysis helps teams interpret that stream as an operational signal. It can identify whether a message is positive, neutral, or negative, estimate how strongly the writer feels, and connect sentiment with intent, urgency, topic, and channel context. The useful question isn't merely, “How does the audience feel?” It's, “What should happen to this conversation next?”
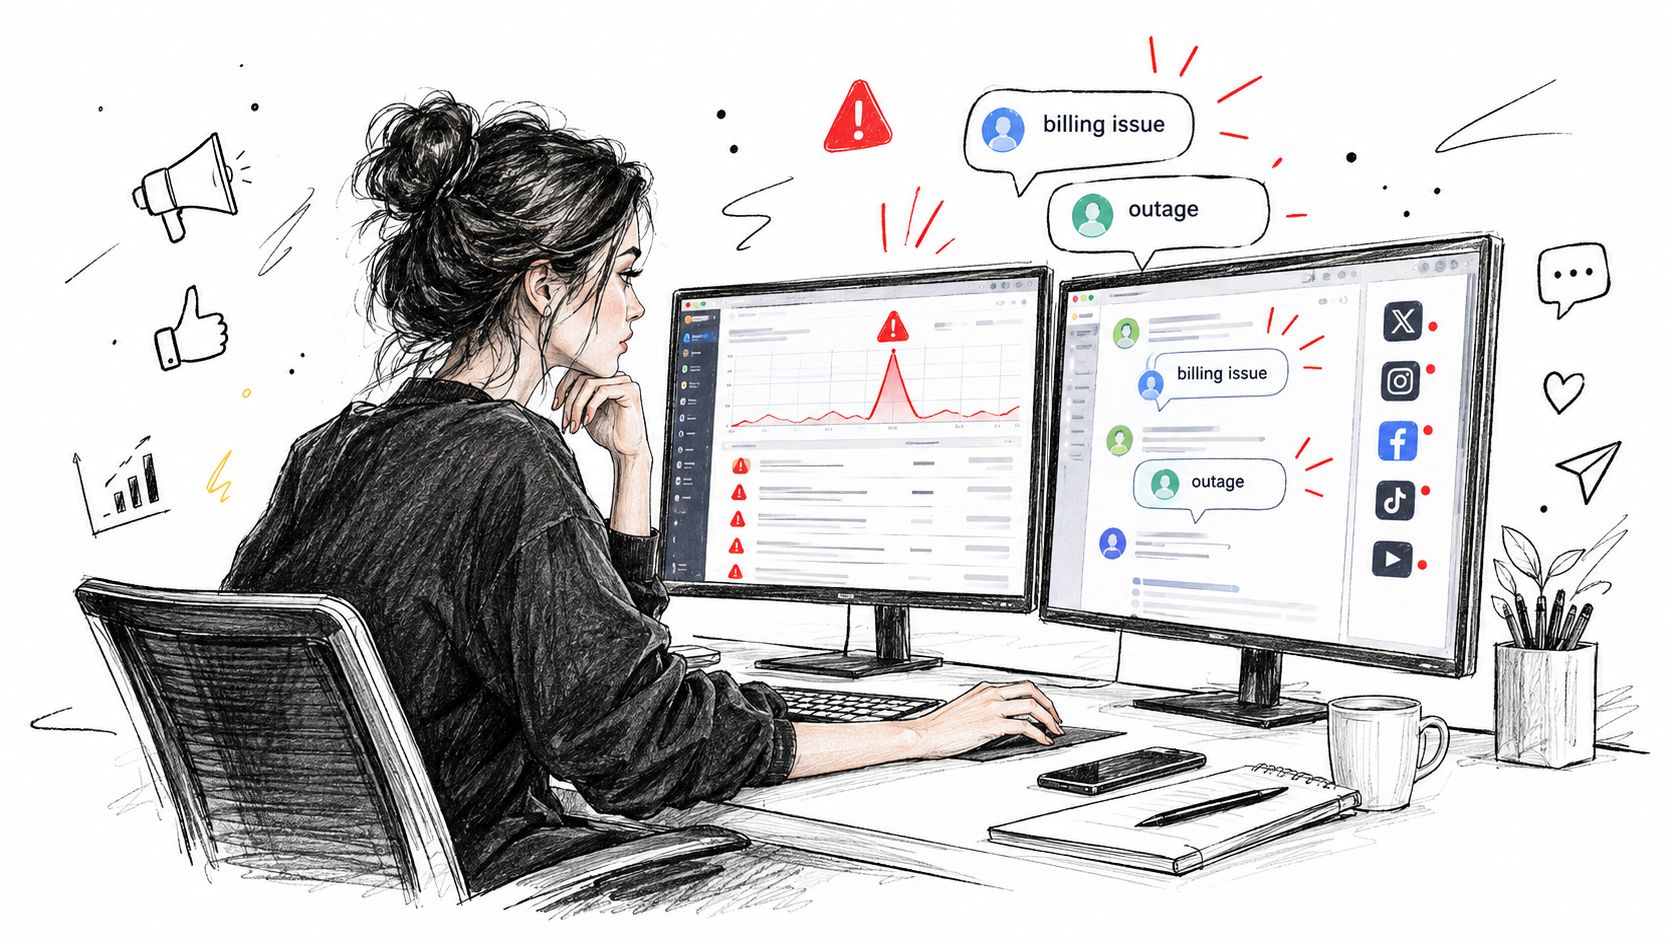
Table of Contents
- Introduction Why Sentiment Signals Matter in Social Operations
- What Social Media Sentiment Analysis Really Does
- How Sentiment Models Work From Lexicons to Transformers
- Why Social Text Breaks Basic Sentiment Models
- Measuring What Matters Accuracy Benchmarks and Evaluation
- Putting Sentiment to Work in Brand and Customer Operations
- Conclusion Building a Reliable Sentiment System With Humans in the Loop
Introduction Why Sentiment Signals Matter in Social Operations
A positive label shouldn't automatically close a thread, and a negative label shouldn't automatically page the crisis team. A customer saying “Love waiting three days for a refund” may need finance, not a celebratory engagement reply. A neutral-looking post that documents an account lockout may deserve faster attention than several enthusiastic comments about a campaign.
That's why sentiment belongs inside the unified inbox, next to intent, urgency, author context, conversation history, and ownership. A model can help filter noise, tag themes, and route likely billing issues to finance, product failures to engineering, and reputational threats to comms. It can draft a response in the approved brand voice, but a human should approve sensitive language, decide whether an issue is urgent, and own the hard call.
The field has a substantial research foundation. A 2022 systematic review of social media-based sentiment analysis has been cited 310 times, and the literature traces broad research interest back to about 2008. That history reflects a practical problem: social platforms produce too much subjective, abbreviated, and context-dependent language for teams to inspect manually.
Operational rule: Sentiment is a routing signal, not a verdict.
For a social care lead, the value appears in workflow outcomes. Reviewers spend less time opening obvious spam, urgent complaints reach the right owner sooner, and auto-closure rules can exclude conversations that contain risk signals. Analysts can also see whether negative sentiment clusters around billing, an outage, a product release, or a policy change instead of reporting one blended brand score.
This article treats sentiment as part of orchestration. The technology should automate noise and prepare the next action. People still approve replies, investigate ambiguous cases, protect brand voice, and decide when support, engineering, trust and safety, or communications must take control.
What Social Media Sentiment Analysis Really Does
A customer posts, “Great, my payment was charged twice.” An inbox that reacts only to “great” may classify the message as positive and send it to the wrong queue. A useful sentiment system works more like a triage nurse. It considers what happened, how serious the signal appears, and which team should review it.
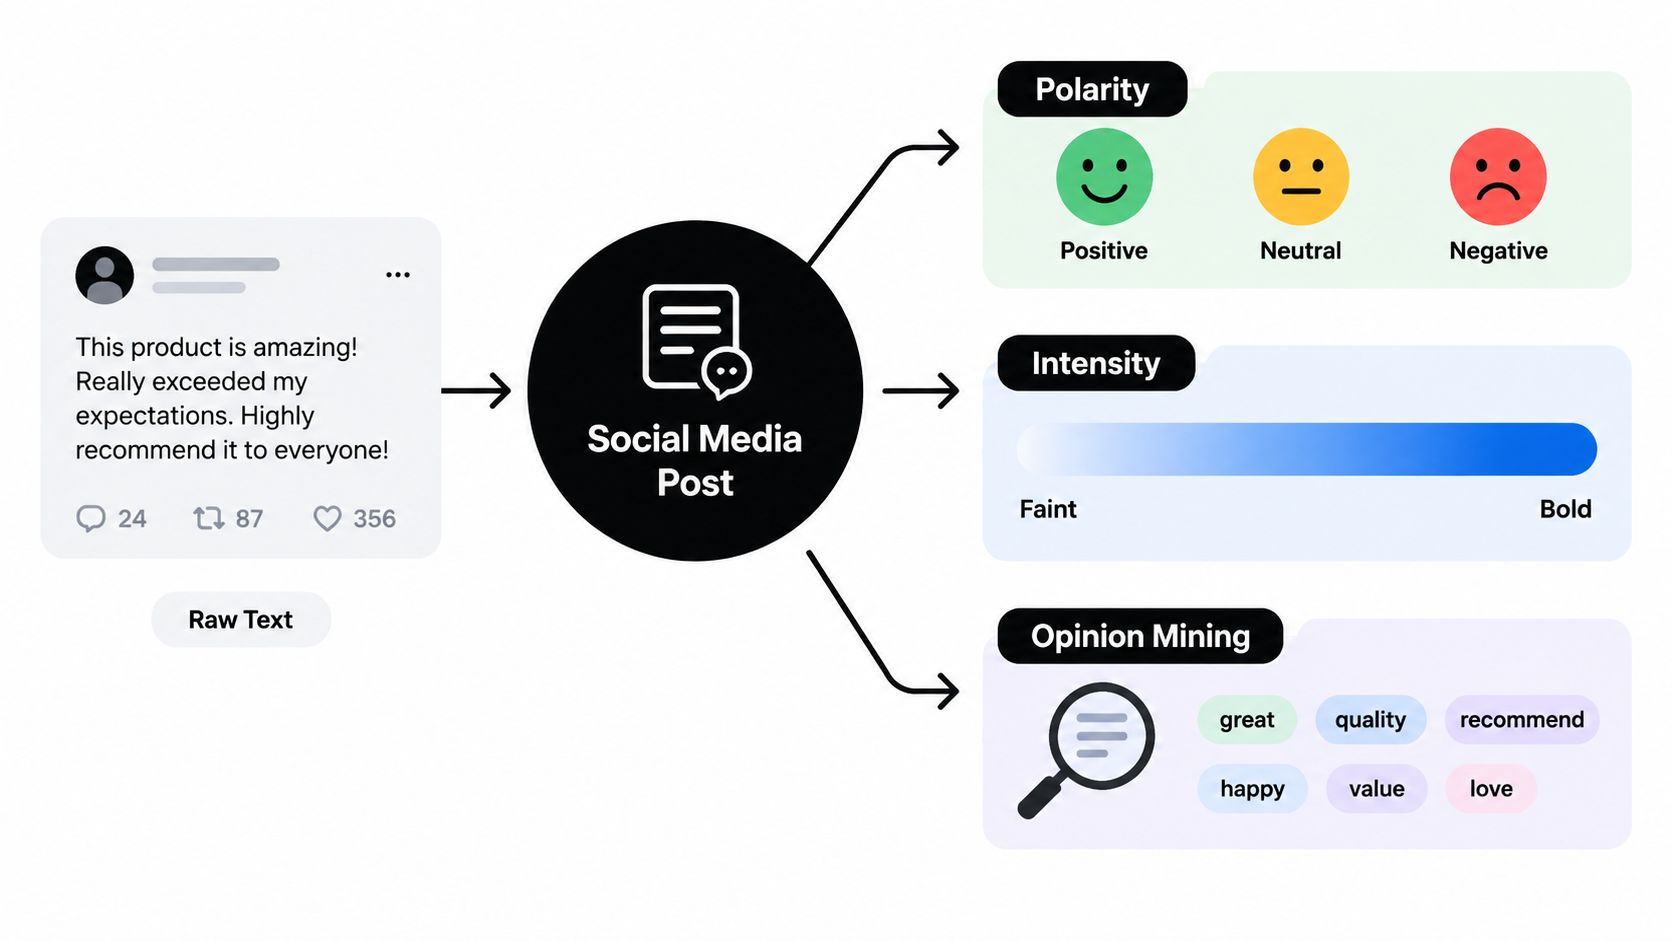
Polarity gives the first signal
Polarity identifies the broad direction of a message:
- Positive: praise, excitement, recommendation, or satisfaction.
- Neutral: factual information, a question without clear emotion, or a simple mention.
- Negative: criticism, frustration, disappointment, or a complaint.
An X reply saying, “The new dashboard is great,” appears positive. A WhatsApp support message using the same word may describe a failed payment. Polarity helps sort an inbox, but it cannot decide the next action by itself.
Intensity separates mild friction from operational risk
Intensity scoring adds strength to the polarity signal. A mild complaint about a color choice belongs in a different review path from an angry post about a failed payment. The distinction becomes more important when a message mentions account access, safety, financial loss, or a public escalation.
Intensity is evidence, not a final severity rating. A dramatic emoji in a playful Discord exchange may carry little operational risk. A restrained forum post may describe a serious defect. Analysts should compare the score with the conversation, account history, and channel norms before escalating or closing anything automatically.
Opinion mining identifies what the person means
Opinion mining connects sentiment to its target. One Instagram comment can praise delivery speed, criticize packaging, and request a missing feature. Assigning one negative label to the entire comment hides those separate signals.
The target changes by platform. On X, it may be a product update. On TikTok, it may be a campaign message or visual joke. On Telegram, it may be a service announcement. In a forum, the meaning may develop across several replies. Hashtags, emojis, slang, language variation, images, and video can all change interpretation, so models need context and human review for ambiguous cases.
Social media sentiment analysis supports work across customer analytics, finance, politics, health, and emergency management. A review of the field's applications describes examples including financial market prediction, health issues, brand valuation, crime prediction, and emergency management. In a unified inbox, the operational question is narrower: should the conversation be routed, escalated, held for review, or closed?
How Sentiment Models Work From Lexicons to Transformers
When a complaint enters a unified inbox, the model affects what happens next. A fast, explainable system may label an obvious billing complaint for review, while a contextual model may detect that praise is sarcastic and route it to an escalation queue. Model choice therefore affects speed, language coverage, reviewer workload, and the safety of auto-closure rules. No architecture removes the need for channel-specific validation.
Lexicon methods are fast and easy to inspect
A lexicon system matches words, expressions, punctuation patterns, and sometimes emojis against a prepared dictionary. VADER is a familiar example for short social posts because it recognizes some emphasis patterns and informal markers without requiring a large custom training process.
The weakness is context. A dictionary may mark “sick” as negative even when a community uses it as praise, or identify “love” while missing sarcastic intent. In one reported experiment, VADER reached 69.52% accuracy on normalized tweets, documented in the study available through the Universidad Rey Juan Carlos repository. That makes a lexicon useful for a first pass, such as separating clear praise from clear complaints, but insufficient as the only production control.
Traditional machine learning learns patterns from labeled examples
Classifiers such as support vector machines learn from examples labeled by humans. Teams can train them on terms, word sequences, punctuation, and other features tied to a product or channel. They are often easier to operate than a large neural system and can perform well when training examples resemble the live queue.
Transfer remains a concern. A classifier trained on product reviews may struggle with an X reply, a Discord meme, or a multilingual Instagram comment. The SentiBench evaluation compared 24 sentiment-analysis methods across 18 labeled datasets, including social-network messages, and found material variation by method and dataset. A benchmark from another text domain should not decide whether an inbox rule can safely escalate or close conversations.
Transformers and LLM-based systems handle broader context
Transformer models examine relationships among words across a message, which helps with longer phrasing, conversation history, and varied expression. LLM-based systems can also classify intent, explain uncertainty, summarize a thread, and draft a response alongside sentiment.
Their trade-offs affect operations. They may cost more to run, need stronger governance, and produce confident errors when examples are rare or language is ambiguous. Multilingual coverage can vary by language and dialect. A model may also misunderstand a meme, image, or video when community culture supplies the missing meaning.
A practical stack assigns different jobs to different methods. A fast classifier filters obvious noise, a contextual model assesses polarity and likely intent, and a human reviews sarcasm, crisis language, financial complaints, or unfamiliar slang. For multimodal posts, visual and text signals should inform routing rather than force an uncertain label. Measure missed escalations, unnecessary reviews, and unsafe auto-closures across the inbox, not only model accuracy.
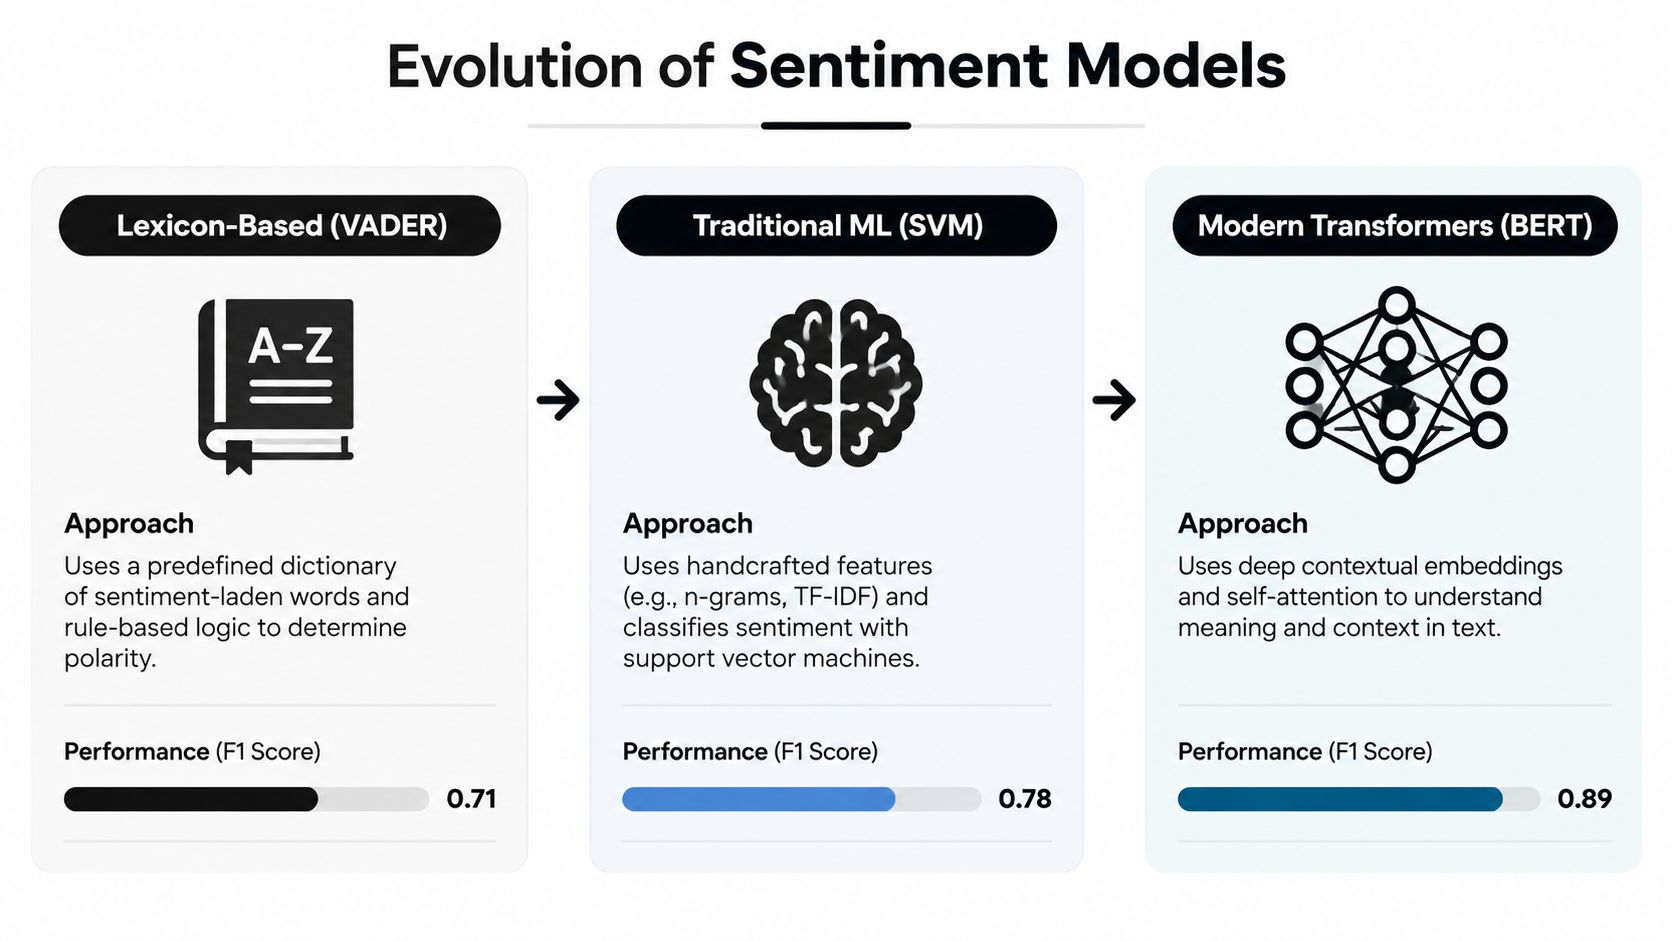
A short visual explanation can help new analysts connect architecture choices with inbox behavior.
Why Social Text Breaks Basic Sentiment Models
Social language carries meaning outside the words themselves. A model that reads only literal text can misclassify the exact messages that matter most during a surge.
Sarcasm reverses the apparent polarity
“Fantastic, another outage” contains a positive adjective and a negative experience. “Support is absolutely crushing it today” may be praise, or it may describe a queue that has failed badly. Sarcasm depends on contrast, shared context, punctuation, timing, and the author's relationship with the brand.
A bilingual English-Malay dataset and sarcasm-aware sentiment study used 10,000 comments and highlighted sarcasm and bilingual language as major challenges. In one LSTM setup, adding sarcasm detection improved reported accuracy from 96.43% to 98.51%, while another setup moved from 93.25% to 95.54%. Those results don't mean every organization will see the same performance. They show why sarcasm should be modeled as a separate signal rather than left to a polarity classifier.
Slang and code-mixing change the meaning of familiar words
Communities invent shorthand quickly. A phrase that signals approval in one Discord server may sound negative to a general-purpose model. A customer might combine English with Malay, Spanish, Arabic, or another language in one WhatsApp message. Typos, abbreviations, repeated letters, and phonetic spelling add more variation.
Keyword rules fail especially when the system has no local vocabulary. A phrase such as “can lah” or a community-specific abbreviation needs cultural and conversational context, not just a translated dictionary. The survey of sentiment analysis and sarcasm detection reviewed 40 research works and explicitly identified multilingual challenges as a central concern.
Emojis, hashtags, images, and memes carry operational evidence
A crying emoji can intensify frustration, express laughter, or react to a joke. Hashtags can frame a post as activism, a campaign response, or an emerging complaint cluster. On TikTok and Instagram, the image or video may contradict the caption. A positive caption over a screenshot of a failed transaction should not be routed as praise.
Formal-text models average only 63.7% accuracy when applied directly to social posts, according to research on multimodal and multilingual sentiment analysis. The same source describes a controlled experiment with a 15–18% accuracy lift over text-only models, while also noting that multimodal systems can still fail on figurative language such as sarcasm.
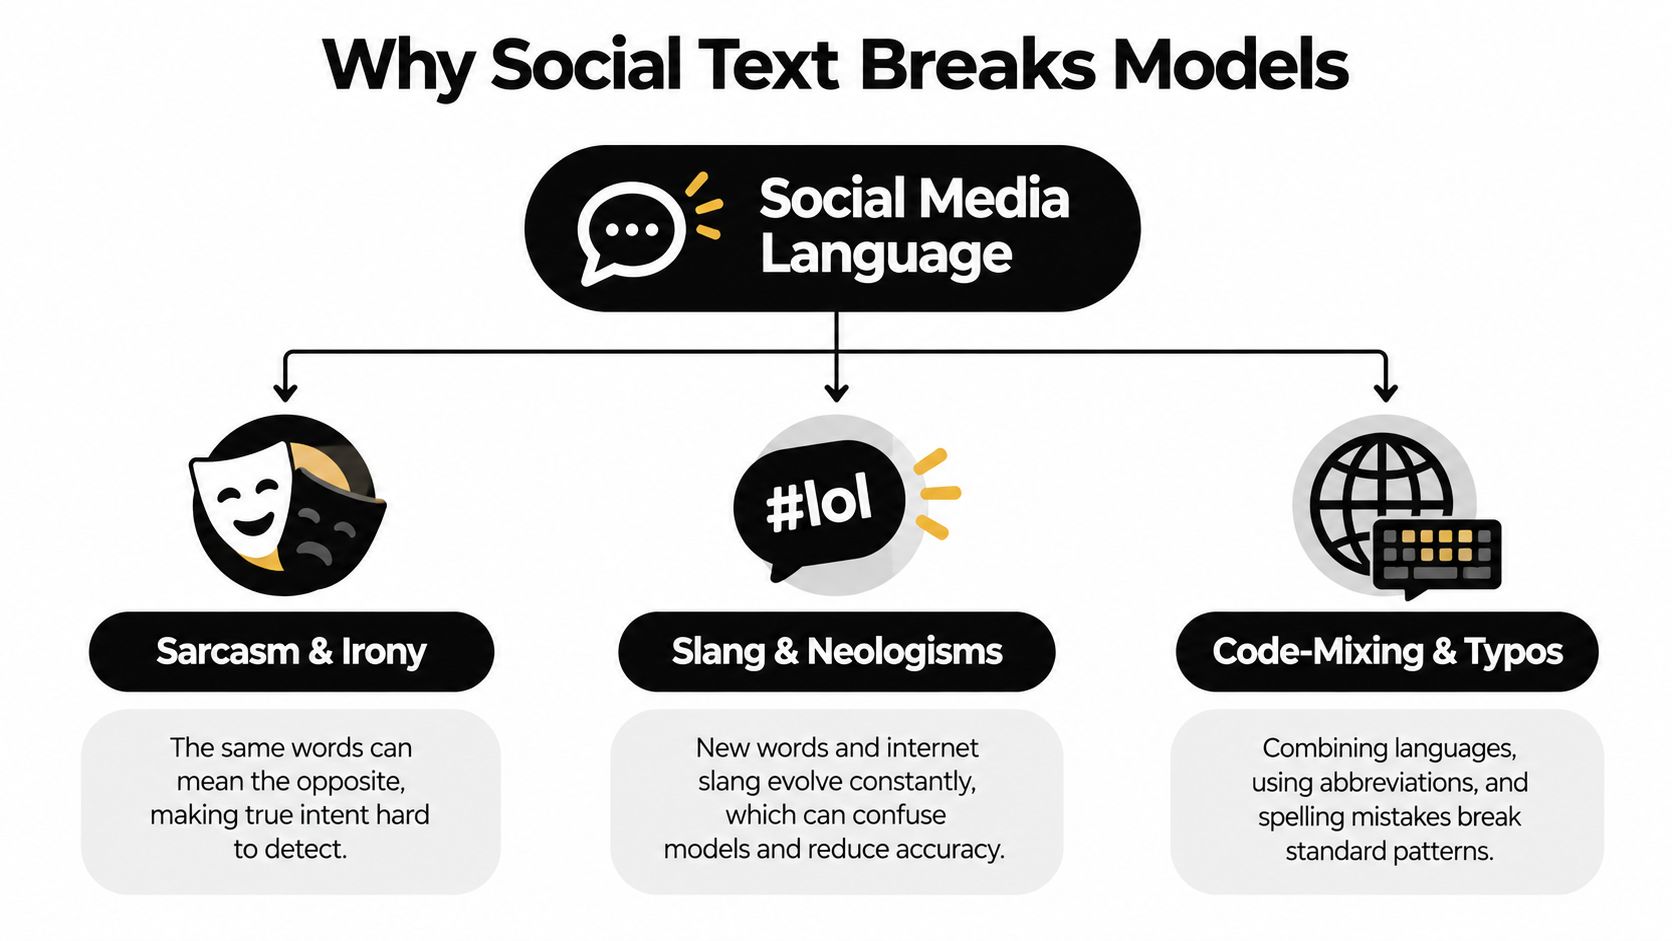
A brittle system often reveals itself through workflow symptoms: angry replies tagged positive, multilingual complaints grouped as neutral, memes ignored, or duplicate spam counted as separate customer issues. Review those errors before allowing sentiment to trigger auto-closure or high-impact routing.
Measuring What Matters Accuracy Benchmarks and Evaluation
A model can earn a strong test score and still send the wrong case to the wrong queue. Evaluation should use labeled examples from your own channels, products, languages, and escalation patterns. In a unified inbox, sentiment is a triage signal. It helps decide what to prioritize, who should review it, and whether auto-closure is safe.
The SentiBench study compared 24 methods across 18 datasets and found that results vary by both method and dataset. A model trained on product reviews may therefore misread an X reply, forum thread, TikTok caption, or private-community message. Treat published benchmarks as a starting point, not proof that a model will transfer to your queue.
Build an evaluation set that reflects the queue
Sample posts from every relevant channel, then include the cases that create reviewer fatigue and routing risk:
- Routine praise: Check whether positive comments can be safely deprioritized.
- Billing and access issues: Test whether negative signals reach finance or support.
- Sarcasm and irony: Include positive wording that carries negative intent.
- Multilingual and mixed-language posts: Ask reviewers familiar with the language and community to label them.
- Images and memes: Test whether visual evidence changes the interpretation.
- Neutral questions: Prevent the system from inflating negative volume when customers are asking for information.
Measure more than aggregate accuracy. Track precision for negative-risk alerts, recall for urgent issues, confusion between neutral and positive, and reviewer overrides. A false negative can delay escalation. A false positive can flood communications teams with noise and increase fatigue. Compare these results by channel and workflow, because an error that is tolerable for praise triage may be unsafe for an access complaint.
| Evaluation Focus | What It Reveals | Operational Implication |
|---|---|---|
| Channel-specific labels | Whether performance transfers across X, Instagram, TikTok, Discord, Telegram, WhatsApp, and forums | Keep routing rules channel-aware |
| Intent and sentiment together | Whether a complaint is also a refund request, bug report, or feature request | Route to finance, engineering, or support |
| Sarcasm and figurative language | Whether literal polarity creates dangerous mislabels | Require human review for ambiguous risk |
| Multilingual and multimodal examples | Whether text-only or single-language models miss local signals | Add language and media-aware review paths |
| Override and escalation patterns | Whether predictions help or burden analysts | Tune confidence thresholds and auto-closure |
Multimodal evidence can change evaluation results materially. One study reported over 90% accuracy across languages after adding emojis, hashtags, and image features, as described in this multimodal sentiment analysis paper. Use that finding to justify testing richer inputs, not to promise the same result for your own data. Before auto-closing a thread, require confidence that covers its polarity, intent, sarcasm risk, and available visual context.
Putting Sentiment to Work in Brand and Customer Operations
Sentiment becomes useful when it changes ownership. A negative score sitting on a dashboard doesn't resolve a payment issue, protect an SLA, or stop a scam wave. The inbox needs rules that combine sentiment with intent, urgency, topic, channel, author, and conversation history.
Consider an outage. X mentions spike, Instagram comments repeat the same failure, and a forum thread includes troubleshooting details. Sentiment can help identify the deterioration, but intent and topic should determine the next step. Route account-specific cases to support, technical symptoms to engineering, and public reputation risk to comms. Give the reviewer a thread summary and a draft response, then keep the final escalation decision with a human.
A separate queue may contain spam and scam waves. Many messages are negative or alarming, but they don't represent individual customer dissatisfaction. Duplicate detection, author patterns, and trust and safety tags should prevent inflated sentiment volume from distorting the social care picture.
The right question isn't “How much negative sentiment do we have?” It's “Which negative conversations need an owner now?”
Feature requests illustrate the opposite problem. A customer may write positively about a product while asking for a missing capability in a Discord channel or DM. If the system uses sentiment alone, the request disappears into praise. Opinion mining and intent tagging can preserve the request and route it to product without treating the customer as an escalation.
For multilingual launches, analysts should inspect local slang, code-mixing, emojis, and visual context before changing auto-closure rules. A high-confidence positive label might be safe for a thank-you message, but not for a sarcastic reaction to a policy announcement. Sift AI can combine a unified inbox with AI filtering, intent and urgency tags, routing, escalation, drafts, and sentiment analytics across social and community channels. Its role in this workflow is to surface and prepare work, while people approve replies and own sensitive decisions.
Track operational measures alongside sentiment trends:
- Noise-filtered percentage: How much irrelevant or duplicate activity the system removes from active review.
- Auto-resolution and auto-closure: Which conversations close safely without hiding unresolved risk.
- Response time and SLA performance: Whether routing gets urgent work to the right team sooner.
- Reviewer overrides: Where the model fails, especially across languages, channels, or media types.
- Proactive saves: Cases where early signals let a team address an issue before it expands.
That combination keeps sentiment connected to care, product, comms, and trust and safety instead of isolating it as a marketing dashboard metric.
Conclusion Building a Reliable Sentiment System With Humans in the Loop
A dependable sentiment program starts with a narrow operational decision. Choose one queue, such as billing complaints in X replies, and define what positive, neutral, negative, urgent, and ambiguous mean for that workflow. Label representative examples, including sarcasm, slang, multilingual posts, images, memes, and duplicate activity.
Then set boundaries before automation begins:
- Route with multiple signals: Combine sentiment with intent, urgency, topic, customer context, and channel.
- Protect high-risk cases: Send financial complaints, safety concerns, crisis language, and public reputation threats to human reviewers.
- Use confidence carefully: Low-confidence predictions should create review work, not trigger automatic closure.
- Measure the queue: Watch SLA, response time, auto-closure rate, reviewer fatigue, overrides, and missed escalations.
- Preserve brand voice: Let AI draft within approved guidance, while humans approve sensitive or public-facing replies.
The mature approach isn't to chase a perfect sentiment score. It's to build a feedback loop in which analysts correct labels, operations leaders adjust routing, and product teams see recurring root causes. AI can automate noise and draft the routine response. Humans still interpret ambiguity, decide priorities, and take responsibility when a conversation carries real customer or reputational risk.
Start with a workflow your team can audit. Compare model decisions with reviewer decisions, inspect failure patterns by channel and language, and expand automation only where the evidence supports it. That's how social media sentiment analysis becomes a reliable operating layer rather than another number nobody trusts.
Sift AI brings conversations from social channels and communities into one operational workspace, then applies sentiment, intent, urgency, routing, escalation, and AI-drafted replies while keeping humans in control. Visit Sift AI to see how your team can turn sentiment signals into faster, more accountable social operations.